Paste a user story → generate executable Playwright pytest tests from your own LLM, on your own machines. Point it at a local or self-hosted model and nothing leaves your network; cloud OpenAI and OpenRouter work too. It even learns from your reference docs — point it at a local model and those stay in-house.
git clone https://github.com/tancat-ai/tancat && cd tancat && uv sync && bash launch_ui.shOne seamless loop that completes end-to-end, with locators taken from the real rendered DOM — not guessed.
Plain language Jira ticket, user acceptance criteria, or markdown spec. That's the only input — no syntax to learn or test framework to master. Or upload a spec doc — the LLM learns from it, and it stays in-house.
TanCat launches headless Chromium, inspects real DOM nodes, builds a page skeleton, and feeds exact attributes to your own LLM. Resolution is score-gated: an unresolved criterion is reported as a skip, never as a guess.
TanCat executes the generated test, records screenshots, and writes out evidence in the shape each role needs: a suite heatmap for the product owner, a Gantt timeline for the test manager, and JUnit/HTML/CSV for the rest.
Locators aren't guessed. TanCat scrapes the live DOM and resolves against real attributes — with score-gated confidence — before it prompts, so every selector traces back to the rendered page.
# Feature: High-Value Wire Confirmation
1. Navigate to /transfers/wire
2. Input amount: “50000”
3. Select beneficiary: “Escrow Alpha”
4. Click “Submit Wire”
5. Verify 2FA modal with ID #two-factor-dialog
import pytest
from playwright.sync_api import Page, expect

@pytest.mark.egress_gated
def test_wire_confirmation_modal(page: Page):
    page.goto("/transfers/wire")
    page.locator('[data-testid="wire-amount-input"]').fill("50000")
    page.locator('select[name="beneficiary"]').select_option("escrow_alpha")
    page.locator('#submit-wire-btn').click()
    modal = page.locator('dialog#two-factor-dialog')
    expect(modal).to_be_visible()
expect(modal).to_contain_text("Confirm Authorization")The Streamlit UI, the tancat CLI, and the CI Action all run the same generation pipeline against your own LLM. There is no second implementation to trust.
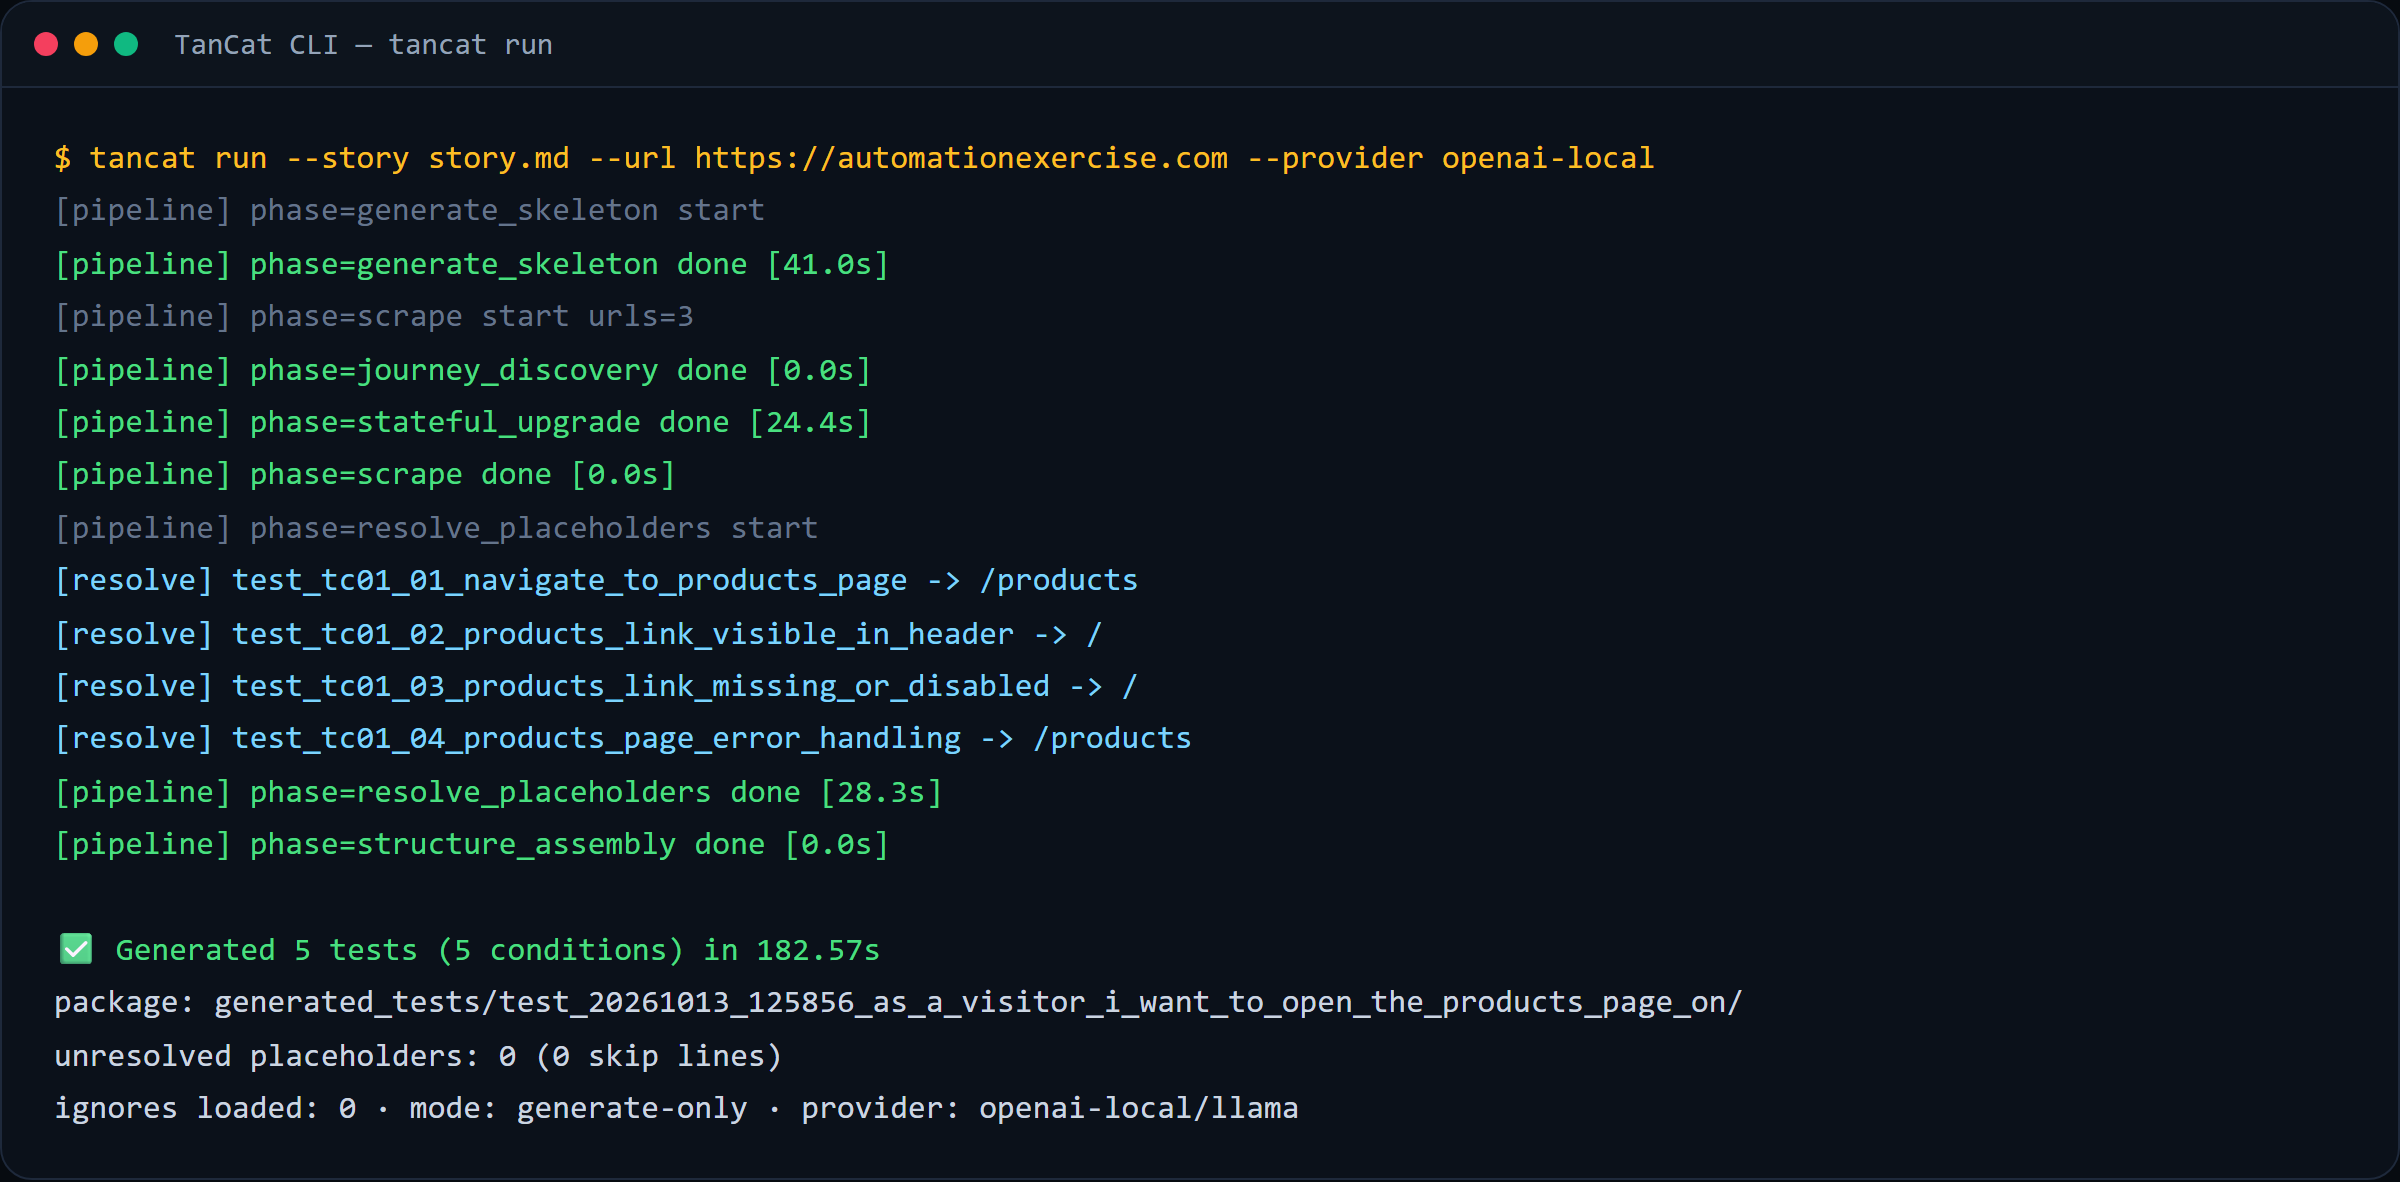
Generate, run, or gate an existing suite from the terminal or your own scripts. Same story, same LLM, same evidence as the UI.
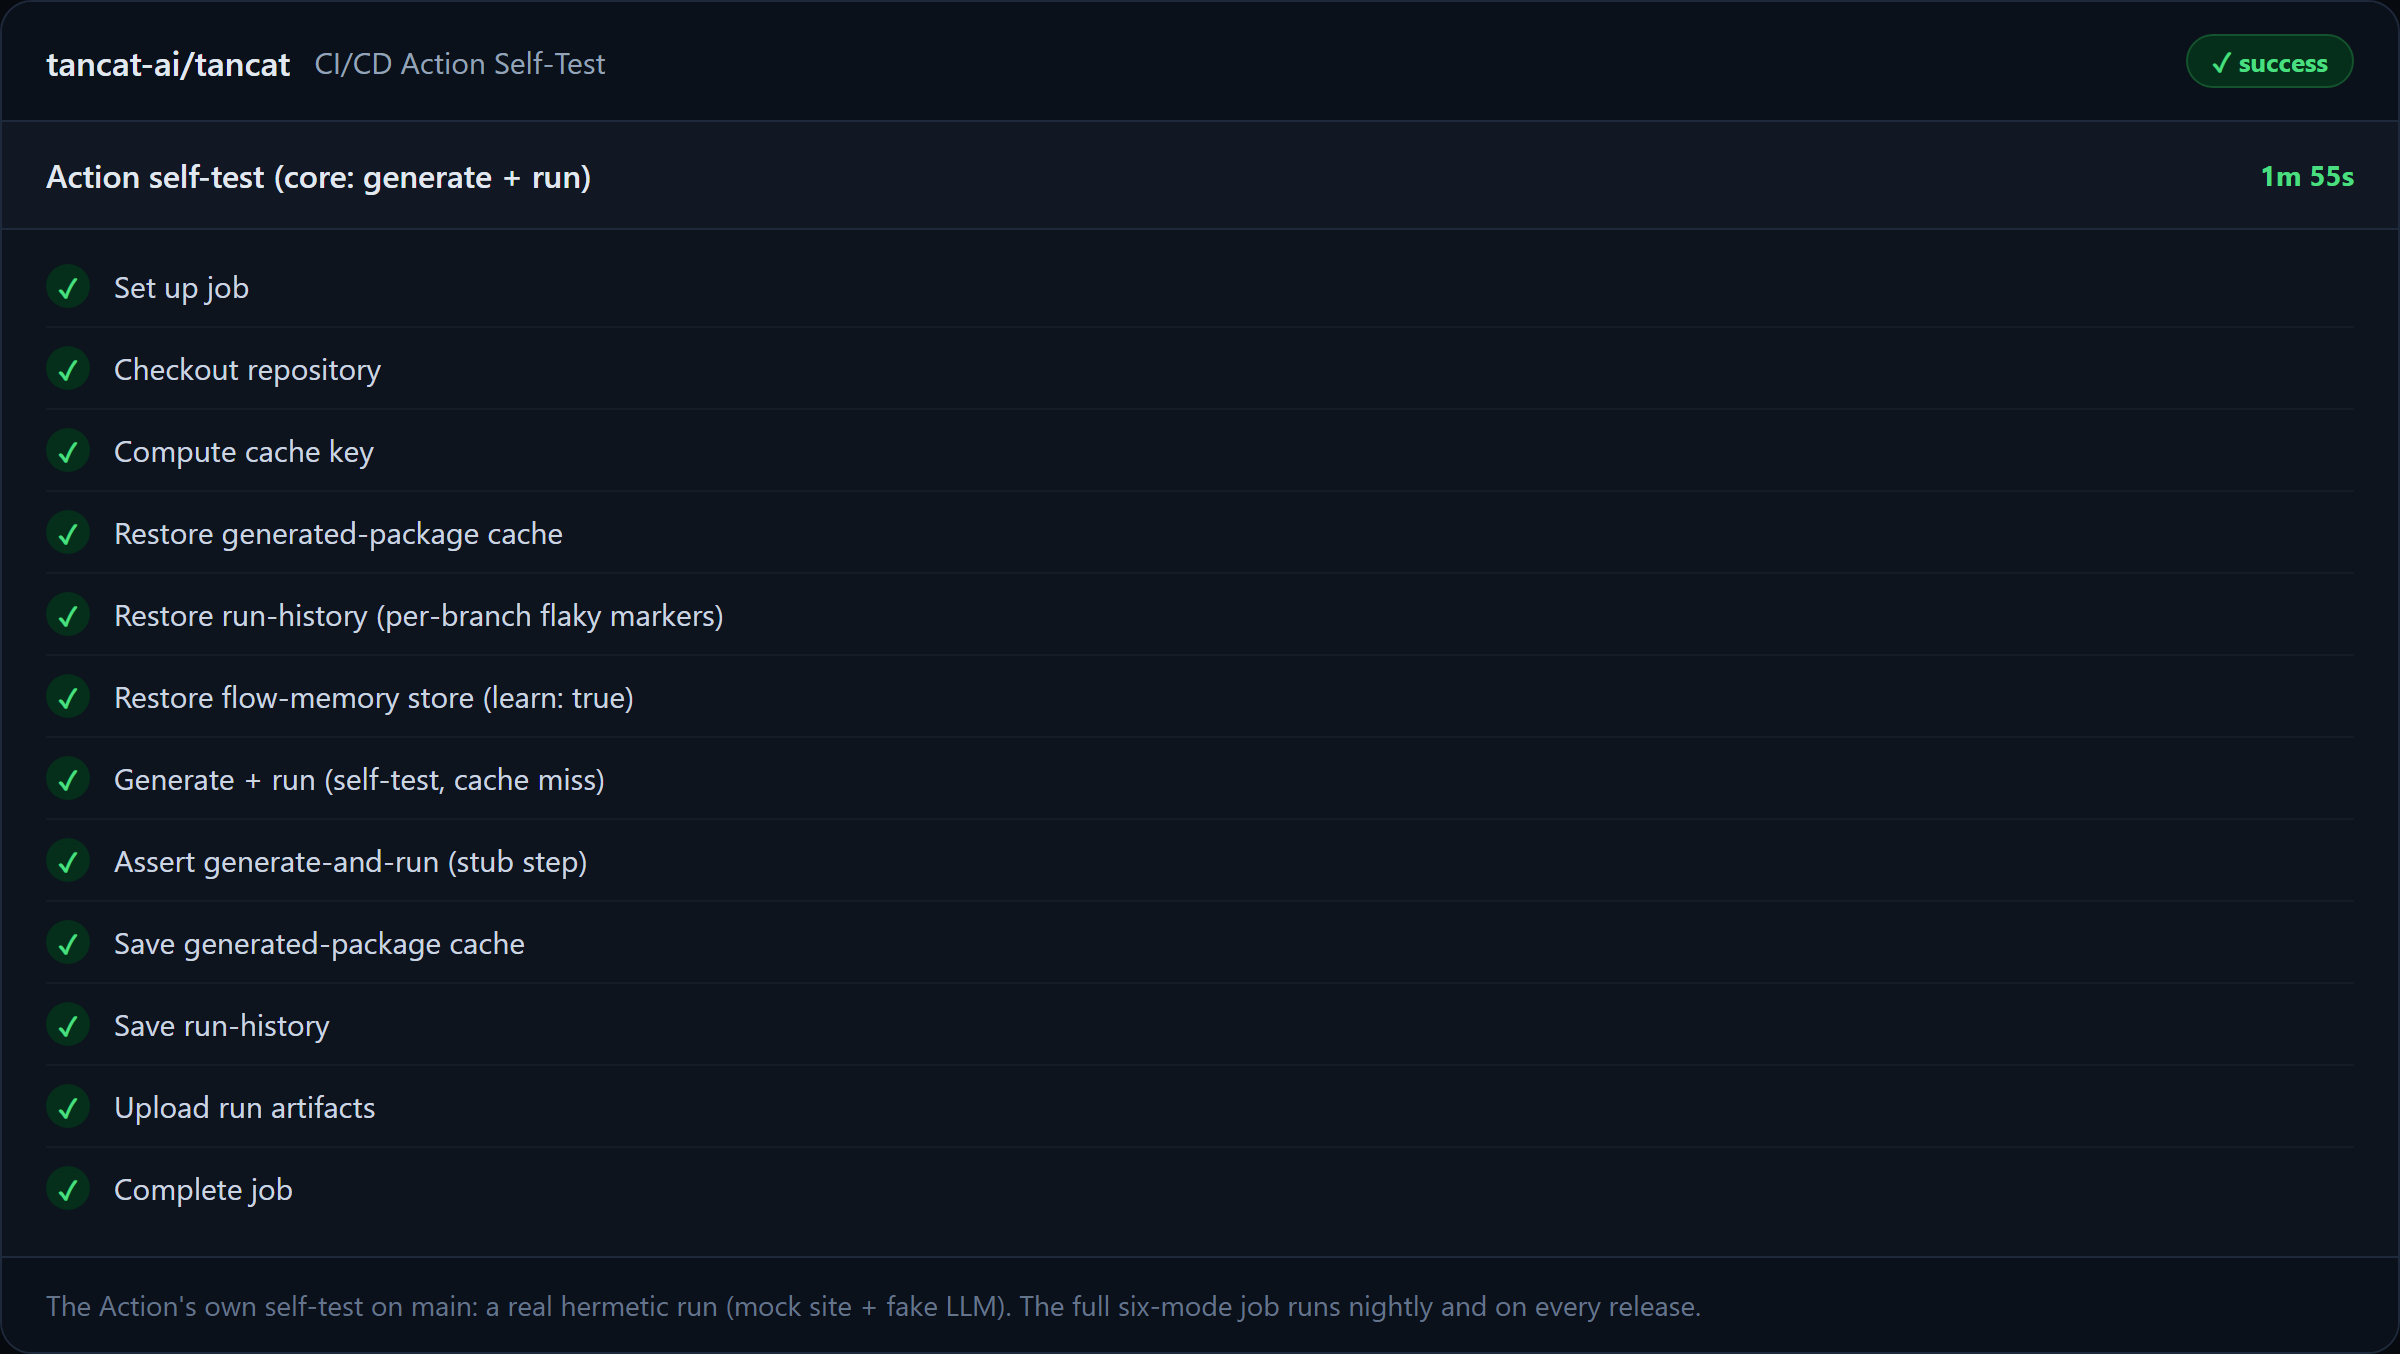
The GitHub Action and the GitLab include template run the same headless pipeline on a pull or merge request: generate (or restore from cache), run pytest as the referee, attach JUnit evidence, and comment the result. The exit code is pytest's, so a red run is your change, not the tool's opinion.
It runs on your runner against your own LLM endpoint - nothing is sent to a vendor cloud. CI reference.
Your LLM, your machines, no vendor cloud. TanCat runs on your machines, pointed at your own LLM, so your customer data stays where you put it.
Native compatibility with llama.cpp, Ollama, LM Studio, or an in-cluster private vLLM endpoint. Swap models anytime with zero vendor lock-in.
Runtime outbound calls are strictly limited to your configured LLM endpoint and your target application. Point it at a local or self-hosted LLM and nothing leaves your network; cloud OpenAI and OpenRouter are supported too. A scan in CI fails the build on any new outbound call site - see the published egress audit.
When markup or CSS class names drift, TanCat re-resolves the locator against the live DOM, patches the test, and re-runs it - after a failure, so the fix is proven by the re-run.
Real evidence, not just a vague checkmark: HTML reports, CSV logs, JUnit XML, and NDJSON (newline-delimited JSON, one record per line).
Organizes test code into maintainable Page-Object-Model (POM) python classes automatically. POM mode and the CI/CD Action are Pro features, and the CI runner must be able to reach your LLM endpoint. Drop the reusable GitHub Action or GitLab CI template into your existing pipelines.
No background calls to PyPI. No tracking beacons. Two components fetch model weights from Hugging Face on first use, and both can be pre-seeded: the RAG embedder, and the optional GPU OCR backend (off by default; OCR_BACKEND=power turns it on). The default OCR path is the CPU one (RapidOCR, offline, and the path that runs today); the GPU OCR path needs CUDA or ROCm, and its live path is untested. A scan in CI fails the build on any new outbound call site. LLM traffic is constrained to your trusted endpoint, and target traffic is strictly SSRF-guarded.
Deploy it once per company, per infra. You should never be penalized when your entire QA and dev squad writes reliable tests.
For solo developers, or for local debugging.
No run caps, and the Jira export, for teams that bill test work to a project.
TanCat uses uv for fast, reproducible dependencies.
uvTell us about your deployment — your stack, your LLM, whether it runs online or fully offline. We’ll set you up with a licence and point you to the right arrangement.
Support is provided by email at hello@tancat.dev, by the developer who builds TanCat. You get help with installation, licensing, and defects in TanCat. We aim to reply within two working days, Monday to Friday, UK business hours. Support does not include custom development, third-party systems, or on-site work, and we do not offer telephone or out-of-hours support. A contractual service level is available on request. Per-deployment pricing · no per-seat charges.
Your message is used only to answer you — see Privacy.